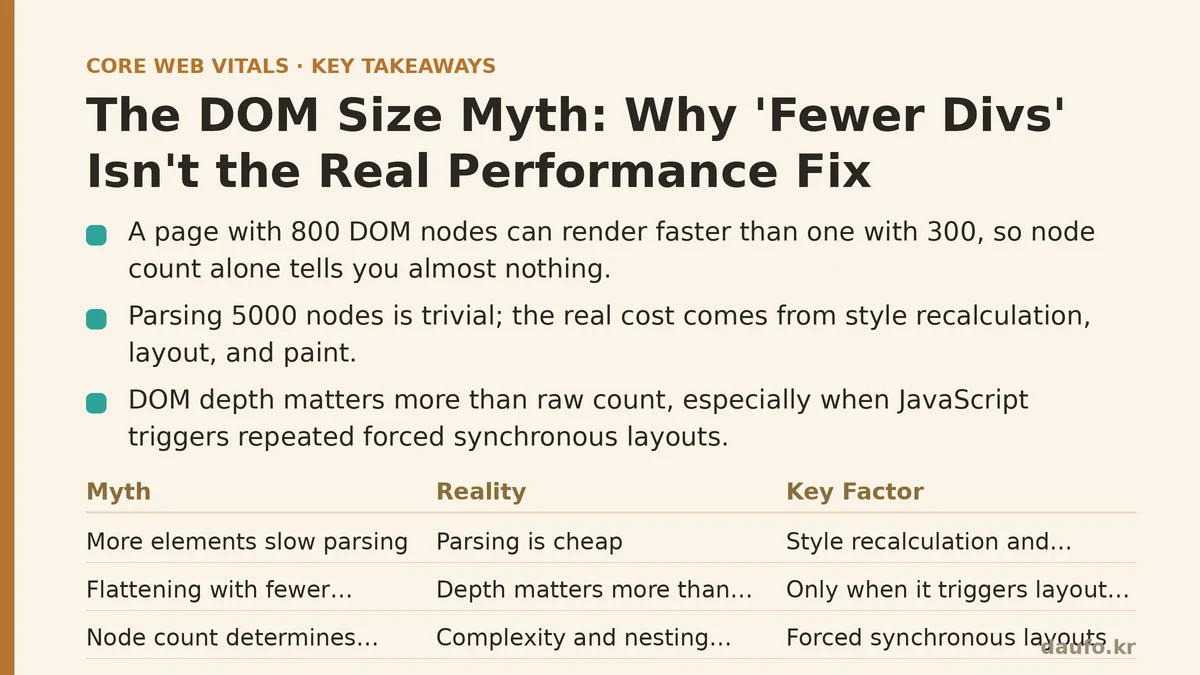
A page with 800 DOM nodes can render faster than one with 300. That single fact breaks most of what developers assume about “reducing DOM size” for performance. Node count alone tells you almost nothing about how a page will actually behave in the browser.
Lighthouse flags “Avoid an excessive DOM size” as though it were a simple counting problem: too many elements, subtract some, ship it. But the audit is measuring a symptom, not the disease. The real cost of a bloated DOM comes from what the browser has to do with those nodes during style calculation, layout, and paint — and that cost scales in ways that a flat node count can’t capture.
This post walks through the most persistent myths about DOM size and performance, and replaces each one with what’s happening under the hood.
Myth #1: “The browser slows down because it has more elements to parse.”
This is the intuitive explanation, and it’s the one most tutorials repeat. More HTML, more parsing work, slower page. Simple.
Reality: Parsing is cheap. Style recalculation and layout are expensive.
Modern browser HTML parsers are extremely fast at turning markup into a DOM tree. Parsing 5,000 nodes takes a trivial amount of time on any device made in the last decade. The bottleneck almost never shows up here.
The real cost appears later, when the browser has to compute the Render Tree. For every element, the browser must resolve which CSS rules apply, cascade and inherit values, and then calculate the geometry (position, size) of every box on the page. This is where complexity compounds.
Picture a warehouse with 5,000 identical boxes stacked in a single row. Checking each one is fast because the rule is the same for all of them. Now picture 800 boxes of wildly different shapes, nested five levels deep, where moving one box forces the recalculation of dozens of others around it. The second warehouse is smaller but far more expensive to manage. DOM size is the box count; DOM complexity is the shape and nesting of those boxes — and complexity is what costs you milliseconds.
Myth #2: “A flat DOM structure with fewer wrapper divs solves the problem.”
Developers who take this myth seriously start aggressively flattening markup, stripping out semantic wrappers, and collapsing nested containers into single elements wherever possible.
Reality: Depth matters more than raw count, but only when it triggers cascading layout work.
DOM depth — how many levels of nesting exist from the root to a given element — has a much stronger correlation with layout cost than total node count. Every additional level of nesting is another link in the chain the browser must walk when it resolves inherited styles or recalculates geometry after a change.
Here’s the part that’s easy to miss: depth only becomes expensive when something changes. A deeply nested but static page can sit there all day without costing you anything after the first paint. The real damage happens when JavaScript mutates a deeply nested element and triggers what’s known as layout thrashing — repeated, forced synchronous recalculations of layout.
// Problematic: forces layout recalculation on every iteration
for (let i = 0; i < items.length; i++) {
  items[i].style.width = box.offsetWidth + 'px'; // read
  items[i].classList.add('updated');              // write
}
Reading a layout property (offsetWidth) immediately after writing one (style.width) forces the browser to flush any pending layout changes and recalculate immediately, rather than batching the work. Do this inside a loop across deeply nested elements, and you get dozens of forced synchronous layouts in a single frame. That’s the actual mechanism behind the “slow DOM” people blame on node count.
Myth #3: “Reducing DOM size is mainly about improving load time.”
This is a reasonable assumption, since most performance advice is framed around getting the page to appear faster. Fewer elements should mean less for the browser to deal with before the first paint, right?
Reality: The bigger cost shows up during interaction, not initial load.
A static page with a large DOM might paint just fine on first load, especially if the layout is simple and styles are predictable. The real tax comes due later, every time something on the page changes: a class toggle, a resize, a scroll-triggered animation, a dynamic list update.
This is why DOM size shows up directly in Core Web Vitals through Interaction to Next Paint (INP) rather than through Largest Contentful Paint. Every user interaction — a click, a keystroke, a hover state — can trigger style recalculation and layout across some portion of the tree. The larger and more complex that tree, the longer the browser needs to figure out what changed and repaint it.
A few concrete triggers worth watching for:
- Toggling a class on a high-level ancestor. If that ancestor has thousands of descendants, the browser may need to recheck styles for all of them, even if most weren’t affected.
- Resizing a flex or grid container. Layout algorithms for flexbox and grid are more computationally expensive than block layout, and they get costlier with more children and more nesting.
:has()and other relational selectors. These require the browser to evaluate relationships between elements, which scales with tree size and structure.
Myth #4: “There’s no real threshold — just make it ‘as small as possible.’”
Without a concrete number, “reduce your DOM size” becomes advice nobody can act on. It sounds like a best practice with no measurable target.
Reality: There are documented thresholds, and Lighthouse uses them directly.
Lighthouse’s DOM size audit flags pages that cross specific thresholds:
- More than 800 DOM nodes triggers a warning.
- More than 1,400 DOM nodes triggers a failing score.
- A maximum DOM depth greater than 32 levels is flagged separately.
- A parent element with more than 60 child elements is flagged separately as well.
These numbers aren’t arbitrary. They correlate with observed increases in style recalculation and layout time across real-world pages tested by the Chrome team. Treat them as warning signs worth investigating, not hard limits that guarantee a fast page once you’re under them. A page with 750 nodes and a deeply nested, interaction-heavy component can still perform worse than a page with 1,200 flat, static nodes.
What To Do Instead of Counting Nodes
Rather than chasing a node count target, focus on the structural patterns that cause layout and style recalculation costs to spike.
- Virtualize long lists. If you’re rendering hundreds of rows in a table or feed, only render the rows currently visible in the viewport. Libraries like
react-windoworTanStack Virtualhandle this well, and the technique works outside of React too. - Flatten unnecessary wrapper nesting, especially around components that change frequently. A
<div><div><div><span>chain around a frequently updated counter is a common offender. - Batch DOM reads and writes. Separate all your
.offsetWidth,.getBoundingClientRect()reads from your.stylewrites to avoid forced synchronous layouts. - Use
content-visibility: autoon off-screen sections. This tells the browser to skip rendering work for content that isn’t currently visible, which can dramatically cut style and layout costs on long pages. - Audit with the Performance panel, not just node count. Look at the “Recalculate Style” and “Layout” entries in a recorded trace to see where time is going, rather than relying on total DOM size as a proxy.
The Real Framework: Size, Depth, and Volatility
| Factor | What It Measures | When It Matters Most |
|---|---|---|
| Total node count | Raw number of DOM elements | Mostly during memory usage and initial style computation |
| Tree depth | Levels of nesting from root to leaf | During any style or layout recalculation triggered by change |
| Child count per parent | Siblings under a single element | During flex/grid layout and selector matching |
| Volatility | How often a subtree changes via JS | The single biggest factor in real-world INP degradation |
Node count is the easiest of these four to measure, which is probably why it became shorthand for the whole problem. But volatility — how often a section of the DOM changes after load — is the one that determines whether users notice anything at all.
Before you spend an afternoon flattening markup to shave off a few hundred nodes, record a Performance trace during real interactions on your page. Check whether style recalculation and layout are showing up as bottlenecks, and where in the tree they’re concentrated. That trace will tell you more about your page’s rendering cost than any node count ever will.
Related guides: Animating with Intent: From Janky to Buttery-Smooth 60fps in a Real Dashboard, Mastering Script Loading: A Deep Dive into Async vs. Defer for Peak Performance, and Your DOM Has a Weight Problem: A Step-by-Step Guide to Fixing Excessive DOM Size.
🔗 Recommended Reading
- How to Enable Browser Caching on Your Website: A Beginner's Step-by-Step Tutorial
- Web Performance Monitoring Tools Compared: Lighthouse, PageSpeed Insights, and WebPageTest
- CDN vs. Origin Server: Which to Optimize First for Latency
- Common Mistakes That Break Web Font Performance and How to Fix Them
- Site Speed Optimization for Fintech Websites: Balancing Security, Compliance, and Performance