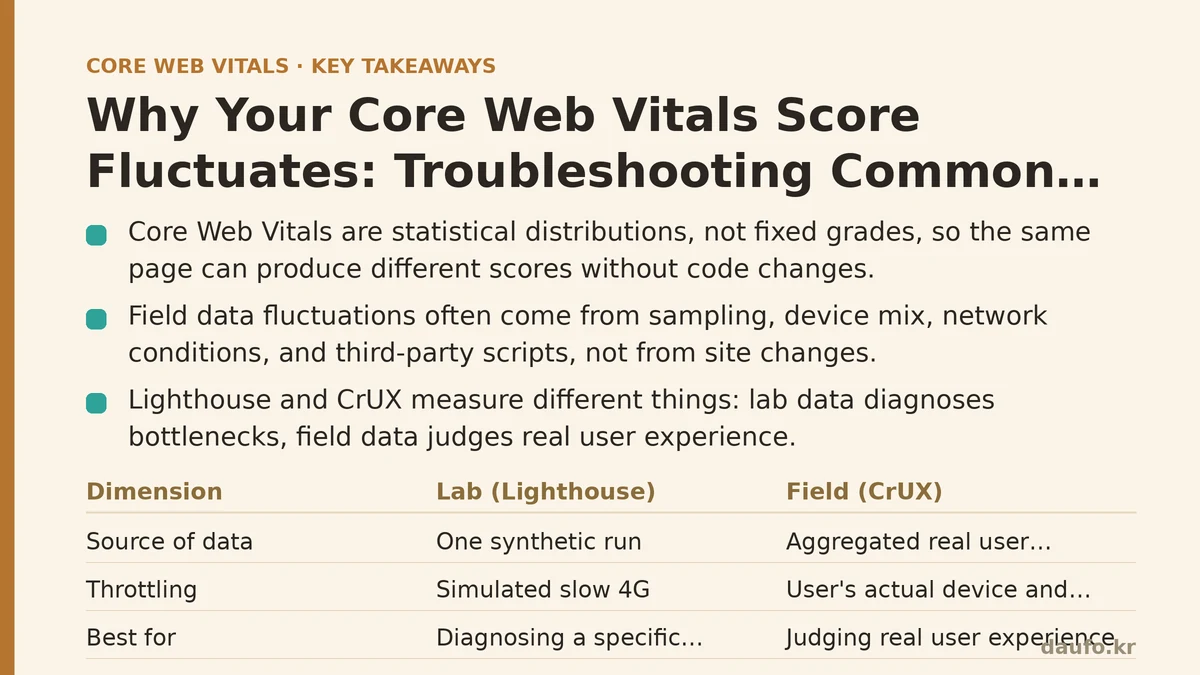
A rising Core Web Vitals score is often treated as proof that an optimization worked, and a sudden drop is treated as proof that something broke. Neither conclusion is safe. Core Web Vitals are statistical distributions, not fixed grades, and the same page measured twice can produce two different verdicts without a single line of code changing.
That is not a bug in the metrics. It is a property of how they are collected. Field data comes from real users on real networks with real devices, and every one of those variables moves. Lab data comes from a synthetic environment that is more controlled, but still sensitive to throttling, caching, and how a run is triggered. Understanding where the noise comes from is the difference between chasing phantom regressions and fixing real ones.
Myth: A score change means the site changed
This is the assumption that wastes the most engineering time. A page reported at a “good” LCP on Monday and “needs improvement” on Wednesday rarely reflects a code change. It reflects a different sample of users, a different device mix, or a different network path.
Reality: most fluctuations come from sampling and environment
CrUX, the dataset behind the public PageSpeed Insights field score, aggregates the 75th percentile of a metric over a rolling 28-day window. That window means any single-day change is diluted across 28 days of prior traffic. A genuine regression that shipped today cannot shift the field score to its final value until the rollout window has fully replaced the old data. Conversely, a field score that “suddenly” drops usually reflects traffic that was already in the pipeline, not the deploy from this morning.
What moves the number:
- Device and network mix. A traffic spike from a slower region or a batch of low-end Android devices can drag the 75th percentile down without any regression.
- Sample size. Low-traffic pages have wide confidence intervals. A page with a few hundred monthly visits can swing tens of percent between runs because the percentile is computed on a thin sample.
- Third-party variance. Ads, tag managers, and chat widgets load conditionally. If a partner script gets slower, LCP or INP follows, and nothing in your repository changed.
- Caching state. First visits and repeat visits have different resource timings. A shift in the ratio of new to returning users shifts the distribution.
None of these are measurement errors in the strict sense. They are the normal texture of field data, and they must be distinguished from genuine regressions before you start reverting commits.
Myth: Lighthouse and CrUX should agree
Teams often run Lighthouse, see a 95 performance score, then open PageSpeed Insights and find a failing field verdict. The instinct is that one of the tools is broken.
Reality: they measure different things in different conditions
| Dimension | Lab (Lighthouse, WebPageTest) | Field (CrUX, RUM) |
|---|---|---|
| Source of data | One synthetic run on emulated hardware | Aggregated real user sessions |
| Throttling | Simulated slow 4G and 4x CPU slowdown | Whatever the user’s device and network happen to be |
| Caching | Cold cache by default; can differ between runs | Mixed cache states across new and returning users |
| Sample | A single trace | 75th percentile over a 28-day window |
| Best for | Diagnosing a specific bottleneck | Judging the experience your users have |
Lighthouse is a diagnostic instrument. It tells you which resource blocked rendering or which element shifted. It is not a forecast of the field score, and treating it as one leads to two failure modes: celebrating a lab score while the field stays red, or panicking over a lab number that real users never experience. Use lab data to find the cause, field data to confirm the effect.
Myth: collecting your own RUM data will settle it
Once a team discovers that page-level field data hides the element-level story, the next step is usually a custom Real User Monitoring integration. That is the right instinct, but only if the collection is done carefully. Sloppy instrumentation produces noisy data that is worse than no data, because it looks authoritative.
Reality: RUM accuracy depends on correct attribution
The Web Vitals library exposes the standard metrics, and the trade-offs are in how you attribute them. A minimal setup using web-vitals looks like this:
import { onLCP, onCLS, onINP } from 'web-vitals';

function send(metric) {
  const body = JSON.stringify({
    name: metric.name,        // 'LCP' | 'CLS' | 'INP'
    value: metric.value,      // numeric value in ms or unitless
    rating: metric.rating,    // 'good' | 'needs-improvement' | 'poor'
    id: metric.id,            // unique per metric instance
    navigationType: metric.navigationType,
    // Add context that explains variance:
    connection: navigator.connection?.effectiveType,
    deviceMemory: navigator.deviceMemory,
    page: location.pathname,
  });

  // sendBeacon survives page unload; fetch(keepalive) is a fallback.
  if (navigator.sendBeacon) {
    navigator.sendBeacon('/rum', body);
  } else {
    fetch('/rum', { body, method: 'POST', keepalive: true });
  }
}

onLCP(send);
onCLS(send);
onINP(send);
Two attribution details break most custom RUM setups:
- Single Page Applications. Without listening to route changes, every metric after the first route gets attached to the initial page load. The result is that one page appears to have enormous LCP values while others appear empty. Report on
popstateand history changes, or use the framework’s router hooks to re-initialize the library. - Late-loading content. LCP is finalized only after the largest element is stable. If you send a beacon on
visibilitychangetoo early, you can capture an interim LCP value that later changes. The library handles this correctly; hand-rolled timers usually do not.
Verify before you trust the pipeline
After wiring up RUM, cross-check the collected values against CrUX for the same URL over a comparable window. Expect differences in exact numbers due to sample composition, but the trend direction and rough magnitude should align. If your RUM reports a 1.8-second LCP while CrUX reports 4.5 seconds for the same page over the same weeks, the instrumentation is measuring a subset of users, or attributing metrics to the wrong page.
Myth: fixing CLS is a one-time task
A common workflow is to measure Cumulative Layout Shift, fix the biggest offenders, and mark the task complete. Then a month later the score creeps back up and the investigation restarts from scratch.
Reality: CLS fluctuates because layout depends on content that changes
CLS is uniquely sensitive to state that lives outside your codebase. Dynamic ad slots, personalized banners, cookie consent overlays, and A/B test variants all inject or resize elements after first paint. Two users can load the same URL and see different layout shifts because they are in different experiment buckets or see different ads.
Diagnostic workflow that produces stable results:
- Ship a layout-shift observer in RUM that records the largest shift target, not just the CLS total. Aggregate by element selector and by page.
- Filter by the variant in your reporting dashboard, so an A/B test variant that shifts layout is not attributed to the control experience.
- Reserve space for every late-injected element with explicit
min-heightor aspect-ratio boxes, so the placeholder matches the final size. - Re-measure after the change, but only compare against a same-variant, same-window baseline. Crossing variants produces false conclusions.
If you skip step 1, you are guessing. The largest shift target is the single most useful piece of data for diagnosing why a page drifts.
When field data is the wrong tool
Field data is the ground truth for user experience, but it is a poor tool for two jobs.
- Debugging a specific interaction. If you need to know why the largest contentful paint element moved, watch a session recording or run WebPageTest. A 75th-percentile field number cannot tell you which element was slow, only that the aggregate experience was slow.
- Validating a change you shipped hours ago. The 28-day window in CrUX means the field signal lags reality. For fast feedback during development, use lab data or a small RUM stream filtered to a canary segment.
The right mix is not “field or lab.” It is lab for causes, RUM for element-level context, and CrUX for the authoritative verdict. Each answers a different question, and conflating them is the root of most Core Web Vitals panic.
The next time a score moves, resist the urge to open the deploy log first. Check the sample size, the device mix, the variant buckets, and the cache ratio before you assume the code is at fault. More often than not, the needle moved because the population behind the number did.
Related guides: Common Core Web Vitals Mistakes Developers Make (And How to Fix Them), Core Web Vitals Optimization for Finance and Banking Websites: A Troubleshooting Checklist, and Next.js Performance Optimization: Five Priority Fixes That Move Your Core Web Vitals.
🔗 Recommended Reading
- How to Enable Browser Caching on Your Website: A Beginner's Step-by-Step Tutorial
- Web Performance Monitoring Tools Compared: Lighthouse, PageSpeed Insights, and WebPageTest
- CDN vs. Origin Server: Which to Optimize First for Latency
- Common Mistakes That Break Web Font Performance and How to Fix Them
- Site Speed Optimization for Fintech Websites: Balancing Security, Compliance, and Performance